
Anthropic
Building the JDBC URL
After installing the license, open the connection management page by running java -jar kingswaysoft.jdbc.jar. Enter the required details to generate the JDBC connection URL. Click Test Connection to test the generated URL, or Copy to Clipboard to copy the connection string for use in your application.
Note: If the license is not installed, you can still use the connection manager to generate a JDBC URL; however, the 'Test Connection' feature will be disabled.
General Page
The General page of the Anthropic Connection Manager allows you to specify the general settings of the connection:
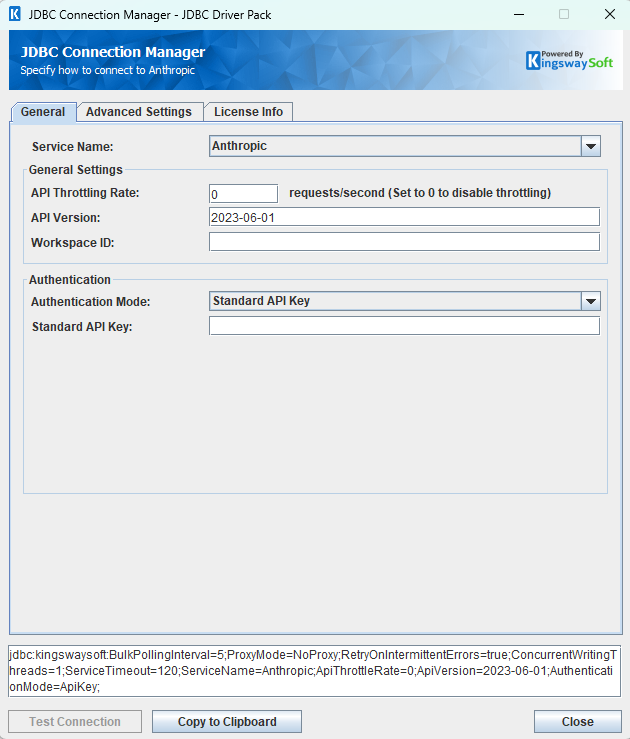
General Settings
- Version
-
The Version option specifies the Anthropic API version sent with each request in the
anthropic-versionheader. The default value is2023-06-01. You can leave this as-is unless you need to use a different version. - Workspace ID
-
The Workspace ID option is optional. When a value is provided, it is either sent in the
anthropic-workspace-idheader or in the JSON request body, depending on the authentication type used.When using either Standard API Key or Admin API Key authentication, it is sent in the header. If no value is provided for Workspace ID, it causes the
anthropic-workspace-idheader to not be sent in requests.When using Workload Identity Federation authentication, Workspace ID is sent in the JSON request body. If no value is provided for Workspace ID, it is still sent in the request body but as an empty string.
- API Throttle Rate
-
The API Throttle Rate limits the number of requests that can be sent per minute. Set this value to 0 to disable API throttling.
Authentication
- Authentication Mode
-
The Authentication Mode option allows you to choose the method used to authenticate with the Anthropic API. Available options are:
- Standard API Key
- Admin API Key
- Workload Identity Federation
Authentication Methods for Anthropic
Standard API Key
Use a Standard API Key to authenticate with the Anthropic API for workspace-scoped operations such as messages, files, and skills.
- Standard API Key
-
The Standard API Key option allows you to set the API key that will be used to authenticate requests to the Anthropic API. Get your API key through the Anthropic Console.
Admin API Key
Use an Admin API Key to authenticate with the Anthropic Admin API for organization-level operations such as users, workspaces, API keys, and usage reports.
- Admin API Key
-
The Admin API Key option allows you to set the Admin API key that will be used to authenticate requests to the Anthropic Admin API. Get your Admin API key through the Anthropic Console.
Workload Identity Federation
Use Workload Identity Federation to authenticate with Anthropic by providing an assertion directly. The driver sends that value in the token exchange request and then uses the returned access token for later API calls. A path to an identity token file is not used.
The token request is posted to https://api.anthropic.com/v1/oauth/token with this JSON body:
{
  "grant_type": "urn:ietf:params:oauth:grant-type:jwt-bearer",
  "assertion": "123123123123123123123123",
  "federation_rule_id": "123",
  "organization_id": "321",
  "service_account_id": "123",
  "workspace_id": ""
}
- Assertion
-
The Assertion option is where you enter the identity assertion. The value is sent as the
assertionfield in the token request. This field is required. - Federation Rule ID
-
The Federation Rule ID option specifies the federation rule ID used for the Workload Identity Federation exchange. This field is required.
- Organization ID
-
The Organization ID option specifies the Anthropic organization ID for the connection. This field is required.
- Service Account ID
-
The Service Account ID option specifies the Anthropic service account ID associated with the federation rule. This field is required.
Advanced Settings Page
The Advanced Settings page allows you to specify advanced settings for the connection.
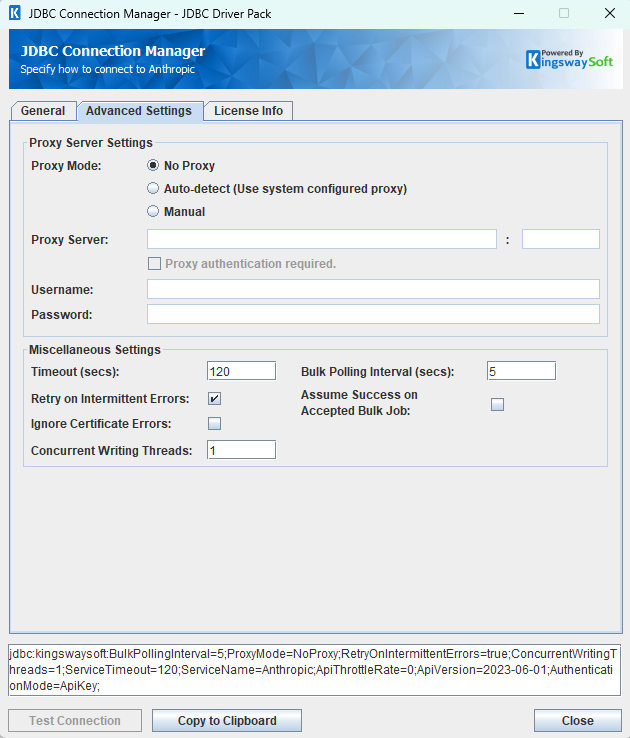
Proxy Server Settings
- Proxy Mode
-
The Proxy Mode option allows you to specify how you want to configure the proxy server setting. There are three options available.
- No Proxy
- Auto-detect (Use system configured proxy)
- Manual
- Proxy Server
-
Using the Proxy Server option allows you to specify the name of the proxy server for the connection.
- Port
-
The Port option allows you to specify the port number of the proxy server for the connection.
- Username (Proxy Server Authentication)
-
The Username option (under Proxy Server Authentication) allows you to specify the proxy user account.
- Password (Proxy Server Authentication)
-
The Password option (under Proxy Server Authentication) allows you to specify the proxy user's password.
Miscellaneous Settings
- Timeout (secs)
-
The Timeout (secs) option allows you to specify a timeout value in seconds for the connection. The default value is 120 seconds. Specify 0 for infinite timeout.
- Retry on Intermittent Errors
-
The retry on intermittent errors determines if requests will be retried when there is an error. If this option is checked requests will be retried up to 3 times.
- Ignore Certificate Errors
-
This option can be used to ignore those SSL certificate errors when connecting to the target server.
Warning: Enabling the "Ignore Certificate Errors" option is generally NOT recommended, particularly for production instances. Unless there is a strong reason to believe the connection is secure - such as the network communication is only happening in an internal infrastructure, this option should be unchecked for best security.
Note: When this option is enabled, it applies to all HTTP-based SSL connections in the same job process.
- Concurrent Writing Threads
-
This option can be used to set the number of threads to be used during write operations. This can improve performance during large-volume write operations.
- Bulk Polling Interval (secs)
-
This value controls how often (in seconds) the driver polls Anthropic to check the status of Message Batch operations until processing has ended or been canceled. It is used when Assume Success on Accepted Bulk Job is selected.
- Assume Success on Accepted Bulk Job
-
When this option is not selected (the default), the driver returns the Message Batch ID immediately after Anthropic accepts the job, without waiting for processing to finish. When this option is selected, the driver polls Anthropic at the Bulk Polling Interval until the batch reaches a completed or canceled status.
Using the JDBC Driver
This section provides examples that use JDBC classes such as Connection, Statement, and ResultSet to manage interactions with Anthropic data. It covers regular statements and prepared statements for complex or frequently executed queries.
Executing Statements
After you have connected from your code, you can execute SQL statements using the Statement class. For connection details, see Connecting with DriverManager or Connecting with DataSource. For parameterized statements, see Executing Prepared Statements.
SELECT
Use the Statement class's generic execute method or the executeQuery method to execute SQL statements that return data. To retrieve the results of a query, call the getResultSet method of the Statement.
String sql = "SELECT * FROM organizations/invites";

try {
    ResultSet resultSet = statement.executeQuery(sql);
    LOGGER.info(resultSet.toString());
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
INSERT
Use either the generic execute method or the executeUpdate method of the Statement class to execute an INSERT operation.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the inserted data's ID, exceptions raised during execution, and details of the affected data.
String sql = "INSERT INTO organizations/invites (email, role) VALUES ('[email protected]', 'billing')";

try {
    statement.executeUpdate(sql);
    LOGGER.info(statement.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
id,errorcode,errormessage,processdata,haserrors
invite_015gWxCN9Hfg2QhZwTK7Mdeu,null,null,{"email":"[email protected]","role":"billing"},false
To create a Skill, see Skills and Skill Versions.
UPDATE
Use either the generic execute method or the executeUpdate method of the Statement class to execute an UPDATE operation.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the updated data's ID, exceptions raised during execution, and details of the affected data.
String sql = "UPDATE organizations/workspaces SET name = 'Updated Workspace Name' WHERE workspace_id = 'wrkspc_01JwQvzr7rXLA5AGx3HKfFUJ'";

try {
    statement.executeUpdate(sql);
    LOGGER.info(statement.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
id,errorcode,errormessage,processdata,haserrors
wrkspc_01JwQvzr7rXLA5AGx3HKfFUJ,null,null,{"name":"Updated Workspace Name"},false
DELETE
Use either the generic execute method or the executeUpdate method of the Statement class to execute a DELETE operation.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the deleted data's ID, exceptions raised during execution, and details of the affected data.
String sql = "DELETE FROM organizations/invites WHERE invite_id = 'invite_015gWxCN9Hfg2QhZwTK7Mdeu'";

try {
    statement.executeUpdate(sql);
    LOGGER.info(statement.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
id,errorcode,errormessage,processdata,haserrors
invite_015gWxCN9Hfg2QhZwTK7Mdeu,null,null,null,false
Executing Prepared Statements
Using a PreparedStatement can improve performance when you need to execute a SQL statement multiple times with different parameters. Unlike a Statement object, a PreparedStatement object is provided with a SQL statement when it is created, which can then be executed with different values each time. This special type of statement is derived from the more general Statement class.
Below are the steps outlining how to execute a prepared statement:
Creating and Executing a Prepared Statement
- Create a PreparedStatement
-
Use the
prepareStatementmethod of theConnectionclass to instantiate aPreparedStatement.For connection details, see Connecting with DriverManager or Connecting with DataSource.
- Set Parameters
- Declare parameters by calling the corresponding setter method of the
PreparedStatement. - NOTE: The parameter indices start at 1.
- Execute the PreparedStatement
- Use the generic
executeorexecuteUpdatemethod of thePreparedStatement. - Retrieve Results
- Call the
getResultSetmethod of thePreparedStatementto obtain the query results, which are returned as aResultSet. - Iterate Over the Result Set
- Use the
nextmethod of theResultSetto iterate through the results. To obtain column information, use theResultSetMetaDataclass. Instantiate aResultSetMetaDataobject by calling thegetMetaDatamethod of theResultSet.
SELECT
Use the PreparedStatement class's generic execute method or the executeQuery method to execute SQL statements that return data.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the retrieved data.
String sql = "SELECT * FROM organizations/invites WHERE invite_id = ?";

try {
    PreparedStatement ps = connection.prepareStatement(sql);
    ps.setString(1, "invite_015gWxCN9Hfg2QhZwTK7Mdeu");
    boolean ret = ps.execute();
    if (ret) {
        ResultSet rs = ps.getResultSet();
        LOGGER.info(rs.toString());
    }
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
INSERT
Use either the generic execute method or the executeUpdate method of the PreparedStatement class to execute an INSERT operation.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the ID of inserted data, exceptions raised during execution, and the data affected by the insertion.
String sql = "INSERT INTO organizations/invites (email, role) VALUES (?, ?)";

try {
    PreparedStatement ps = connection.prepareStatement(sql);
    ps.setString(1, "[email protected]");
    ps.setString(2, "billing");
    ps.executeUpdate();
    LOGGER.info(ps.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.error(e);
}
id,errorcode,errormessage,processdata,haserrors
invite_015gWxCN9Hfg2QhZwTK7Mdeu,null,null,{"email":"[email protected]","role":"billing"},false
UPDATE
Use either the generic execute method or the executeUpdate method of the PreparedStatement class to execute an UPDATE operation.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the ID of updated data, exceptions raised during execution, and the data affected by the update.
String sql = "UPDATE organizations/workspaces SET name = ? WHERE workspace_id = ?";

try {
    PreparedStatement ps = connection.prepareStatement(sql);
    ps.setString(1, "Updated Workspace Name");
    ps.setString(2, "wrkspc_01JwQvzr7rXLA5AGx3HKfFUJ");
    ps.executeUpdate();
    LOGGER.info(ps.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.error(e);
}
id,errorcode,errormessage,processdata,haserrors
wrkspc_01JwQvzr7rXLA5AGx3HKfFUJ,null,null,{"name":"Updated Workspace Name"},false
DELETE
Use either the generic execute method or the executeUpdate method of the PreparedStatement class to execute a DELETE operation.
The results of SQL queries are saved in a ResultSet. You can retrieve the ResultSet after execution to view the deleted data's ID, exceptions raised during execution, and details of the affected data.
String sql = "DELETE FROM organizations/invites WHERE invite_id = ?";

try {
    PreparedStatement ps = connection.prepareStatement(sql);
    ps.setString(1, "invite_015gWxCN9Hfg2QhZwTK7Mdeu");
    ps.executeUpdate();
    LOGGER.info(ps.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.error(e);
}
id,errorcode,errormessage,processdata,haserrors
invite_015gWxCN9Hfg2QhZwTK7Mdeu,null,null,null,false
Skills and Skill Versions
Use the skills table to list, look up, create, or delete Skills. Use the skills/versions table to list, look up, create, or delete versions of a Skill. Skills cannot be updated in place; add a new version instead.
When you create a Skill or a Skill Version, put the Skill files in the files column. This column is required. Every Skill must include a SKILL.md file, and all files must be in the same folder.
When creating a Skill, you can optionally set display_name. When creating a version, you also need the existing skill_id.
This files column is not the same as the files table, which is used to upload files for messages.
The files column accepts:
- One Base64-encoded file. The driver uploads it as
skill/SKILL.md. - A JSON list of Base64-encoded files. Each item is uploaded as
skill/SKILL.md. - A JSON list of file objects. Use this when the Skill has more than one file.
Each file object can include:
path(alsofilenameorfile_name) — the file path in the Skill folder, for examplemy-skill/SKILL.md.content(alsofile_content) — required. The file content as a Base64-encoded string.nameanddescription— the Skill name and description. These are used forSKILL.md.content_type(alsofile_content_type) — optional file type. If omitted,text/markdownis used.
If you omit path but provide both name and description, the driver uses the Skill name plus /SKILL.md as the file path, for example my-skill/SKILL.md. If the path is blank or is only SKILL.md, the driver uses skill/SKILL.md.
If SKILL.md does not already include a name and description at the top of the file, the driver adds them for you from the name, description, or display_name values you provided.
You can also pass the file bytes directly with PreparedStatement.setBytes. The driver uploads those bytes as skill/SKILL.md.
String sql = "INSERT INTO skills (files, display_name) VALUES ("
        + "'[{\"path\":\"my-skill/SKILL.md\",\"name\":\"my-skill\",\"description\":\"A sample skill\",\"content\":\"dGVzdDE=\"},"
        + "{\"path\":\"my-skill/reference.md\",\"content\":\"dGVzdDI=\"}]',"
        + "'My Skill')";

try {
    statement.executeUpdate(sql);
    LOGGER.info(statement.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
String sql = "INSERT INTO skills/versions (files, skill_id) VALUES ("
        + "'[{\"path\":\"my-skill/SKILL.md\",\"content\":\"dGVzdDE=\"},"
        + "{\"path\":\"my-skill/reference.md\",\"content\":\"dGVzdDI=\"}]',"
        + "'skill_01JAbcdefghijklmnopqrstuvw')";

try {
    statement.executeUpdate(sql);
    LOGGER.info(statement.getResultSet().toString());
} catch (SQLException e) {
    LOGGER.severe(e.toString());
}
Metadata Discovery
This section provides examples on how to retrieve table and column metadata using the getTables, getColumns, and getPrimaryKeys methods from the DatabaseMetaData interface. These are essential for discovering database structures.
Tables
The getTables method from the DatabaseMetaData interface can be used to retrieve a list of tables.
This method only retrieves tables that are not write-only.
To get a list of tables that includes write-only tables, query the table system.tables.
try {
    Connection connection = buildRestConnectionFromDriverManager();
    ResultSet rs = connection.getMetaData().getTables(null, null, null, null);
    LOGGER.info("\r\n" + rs.toString());
} catch (SQLException e) {
    LOGGER.severe(e.getMessage());
}
TABLE_CAT,TABLE_SCHEM,TABLE_NAME,TABLE_TYPE,REMARKS,TYPE_CAT,TYPE_SCHEM,TYPE_NAME,SELF_REFERENCING_COL_NAME,REF_GENERATION
null,null,organizations/analytics/apps/chat/projects,TABLE,null,null,null,null,null,null
null,null,organizations/analytics/artifacts,TABLE,null,null,null,null,null,null
null,null,organizations/analytics/connectors,TABLE,null,null,null,null,null,null
null,null,organizations/analytics/cost_report,TABLE,null,null,null,null,null,null
......
The getTables method returns the following metadata columns:
| Column Name | Data Type | Description |
|---|---|---|
| TABLE_CAT | String | The catalog that contains the table. |
| TABLE_SCHEM | String | The schema of the table. |
| TABLE_NAME | String | The name of the table. |
| TABLE_TYPE | String | The type of the table (e.g., TABLE or VIEW). |
| REMARKS | String | An optional description of the table. |
Columns
Use the getColumns method of the DatabaseMetaData interface to retrieve detailed information about database columns.
This method returns columns only for tables that are not write-only.
To get columns for write-only tables, query the table system.columns.
try {
    Connection connection = buildRestConnectionFromDriverManager();
    ResultSet rs = connection.getMetaData().getColumns(null, null, "organizations/users", null);
    LOGGER.info(rs.toString());
} catch (SQLException e) {
    e.printStackTrace();
}
TABLE_CAT,TABLE_SCHEM,TABLE_NAME,COLUMN_NAME,DATA_TYPE,TYPE_NAME,COLUMN_SIZE,BUFFER_LENGTH,DECIMAL_DIGITS,NUM_PREC_RADIX,NULLABLE,REMARKS,COLUMN_DEF,SQL_DATA_TYPE,SQL_DATETIME_SUB,CHAR_OCTET_LENGTH,ORDINAL_POSITION,IS_NULLABLE,SCOPE_CATALOG,SCOPE_SCHEMA,SCOPE_TABLE,SOURCE_DATA_TYPE,IS_AUTOINCREMENT,IS_GENERATEDCOLUMN,DTS_TYPE
null,null,organizations/users,added_at,93,TIMESTAMP,null,null,0,0,null,null,null,93,null,null,null,null,null,null,null,null,null,null,DT_DBTIMESTAMP
null,null,organizations/users,email,12,VARCHAR,0,null,0,0,null,null,null,12,null,null,null,null,null,null,null,null,null,null,DT_WSTR
null,null,organizations/users,id,12,VARCHAR,0,null,0,0,null,null,null,12,null,null,null,null,null,null,null,null,null,null,DT_WSTR
null,null,organizations/users,name,12,VARCHAR,0,null,0,0,null,null,null,12,null,null,null,null,null,null,null,null,null,null,DT_WSTR
......
The getColumns method returns the following columns:
| Column Name | Data Type | Description |
|---|---|---|
| TABLE_CAT | String | The database name. |
| TABLE_SCHEM | String | The table schema. |
| TABLE_NAME | String | The table name. |
| COLUMN_NAME | String | The column name. |
| DATA_TYPE | Integer | The data type represented by a constant value from java.sql.Types. |
| TYPE_NAME | String | The data type name used by the driver. |
| COLUMN_SIZE | Integer | The length in characters of the column or the numeric precision. |
| BUFFER_LENGTH | Integer | The buffer length. |
| DECIMAL_DIGITS | Integer | The column scale or number of digits to the right of the decimal point. |
| NUM_PREC_RADIX | Integer | The radix, or base. |
| NULLABLE | Integer | Whether the column can contain null as defined by the following JDBC DatabaseMetaData constants: columnNoNulls (0) or columnNullable (1). |
| REMARKS | String | The comment or note associated with the object. |
| COLUMN_DEF | String | The default value for the column. |
| SQL_DATA_TYPE | Integer | Reserved by the specification. |
| SQL_DATETIME_SUB | Integer | Reserved by the specification. |
| CHAR_OCTET_LENGTH | Integer | The maximum length of binary and character-based columns. |
| ORDINAL_POSITION | Integer | The position of the column in the table, starting at 1. |
| IS_NULLABLE | String | Whether a null value is allowed: YES or NO. |
| SCOPE_CATALOG | String | The catalog of the table referenced by a reference attribute (null if DATA_TYPE is not REF). |
| SCOPE_SCHEMA | String | The schema of the table referenced by a reference attribute (null if DATA_TYPE is not REF). |
| SCOPE_TABLE | String | The name of the table referenced by a reference attribute (null if DATA_TYPE is not REF). |
| SOURCE_DATA_TYPE | Short | The source type of a distinct type or user-defined REF type (null if DATA_TYPE is neither DISTINCT nor a user-defined REF). |
| IS_AUTOINCREMENT | String | Whether the column value is assigned by Anthropic in fixed increments. |
| IS_GENERATEDCOLUMN | String | Whether the column is generated: YES or NO. |
| DTS_TYPE | String | Object DTS attribute type. |
Primary Keys
The getPrimaryKeys method in the DatabaseMetaData interface is used to retrieve metadata about primary keys for a given table in Anthropic.
try {
    Connection connection = buildRestConnectionFromDriverManager();
    ResultSet resultSet = connection.getMetaData().getPrimaryKeys(null, null, "organizations/users");
    LOGGER.info("\r\n" + resultSet.toString());
} catch (SQLException e) {
    LOGGER.severe(e.getMessage());
}
TABLE_CAT,TABLE_SCHEM,TABLE_NAME,COLUMN_NAME,KEY_SEQ,PK_NAME
null,null,organizations/users,id,1,null
The getPrimaryKeys method returns the following columns:
| Column Name | Data Type | Description |
|---|---|---|
| TABLE_CAT | String | The catalog name. |
| TABLE_SCHEM | String | The schema name. |
| TABLE_NAME | String | The name of the table that contains the primary key. |
| COLUMN_NAME | String | The name of the column that serves as the primary key for the table. |
| KEY_SEQ | Short | The sequence number within the primary key. |
| PK_NAME | String | The primary key name. |
Connection Settings
| Connection Setting | Type | Default Value | Description |
|---|---|---|---|
| ApiKey | String | "" | The ApiKey is used to authenticate requests to the Anthropic API when Authentication Mode is Standard API Key or Admin API Key. |
| ApiThrottleRate | Integer | 0 | The maximum number of API requests a client can make to the server per minute. Set this value to 0 to disable throttling. The connection manager stores the unit in ThrottleRateUnit. |
| Assertion | String | "" | The identity assertion entered for Workload Identity Federation. The value is sent as the assertion field in the token exchange request. |
| AssumeSuccessOnAcceptedBulkJob | Boolean | false | When false (default), the driver polls until the Message Batch reaches a completed or canceled status, then returns the job result. When true, the driver assumes the accepted job succeeded and returns the Message Batch ID immediately. |
| AuthenticationMode | String | "ApiKey" | AuthenticationMode specifies the method used to authenticate when connecting to Anthropic API. Allowed values are "ApiKey" (Standard API Key), "AdminApiKey" (Admin API Key), and "WorkloadIdentityFederation". |
| BatchSizeForReading | Integer | 100 | BatchSizeForReading is used to set how many records can be read from Anthropic in a single call. Anthropic has a maximum BatchSizeForReading of 100. |
| BatchSizeForWriting | Integer | 1 | BatchSizeForWriting is used to set how many records can be written to Anthropic in a single call. Batch writing is supported for the messages/batches entity (Create a Message Batch). For other entities, this value should be kept at 1. |
| BulkPollingInterval | Integer | 5 | How often (in seconds) the driver polls Anthropic to check the status of Message Batch operations until processing has ended or been canceled. Used when AssumeSuccessOnAcceptedBulkJob is false. |
| CacheExpirationTime | Integer | 30 | Defines the expiration time for cache. A value of 0 disables caching. |
| ConcurrentWritingThreads | Integer | 1 | The number of threads for executing operations in parallel. A value of 0 will disable multi threading. |
| ConnectionTimeout | Integer | 30 | ConnectionTimeout is the maximum amount of time the program will wait to set up a connection to the Anthropic API. |
| ContinueOnErrors | Boolean | false | Determines if the program continues executing SQL statements after encountering an error. |
| FederationRuleId | String | "" | The federation rule ID sent as federation_rule_id in the Workload Identity Federation token request. |
| IgnoreCertificateErrors | Boolean | false | Specifies whether to verify the certificate when connecting to Anthropic. If no certificate verification is required, you can set this value to 'true'. |
| LogFileSize | String | "10485760" | A string specifying the maximum size in bytes for a log file. |
| LogLevel | String | "INFO" | The logging level for the JDBC driver. |
| LogPath | String | "./jdbcLogs" | The directory where log files are stored. |
| OemKey | String | "" | The OEM license key. |
| OrganizationId | String | "" | The Anthropic organization ID sent as organization_id in the Workload Identity Federation token request. |
| ProxyMode | String | "NoProxy" | This setting configures the proxy. Allowed values are "NoProxy", "AutoDetect" and "Manual". |
| ProxyPassword | String | "" | The password to be used to authenticate to the proxy. |
| ProxyServer | String | "" | The host of the proxy server. |
| ProxyServerPort | Integer | 0 | The port of the proxy server. |
| ProxyUsername | String | "" | The username to be used to authenticate to the proxy. |
| ResultPath | String | "" | The path where the execution result files are saved. |
| RetryOnIntermittentErrors | Boolean | true | The RetryOnIntermittentErrors parameter indicates whether to retry the connection when it might occasionally fail due to temporary issues. |
| SaveResult | Boolean | false | The SaveResult parameter indicates whether to save the execution results to a file. |
| ServiceAccountId | String | "" | The Anthropic service account ID sent as service_account_id in the Workload Identity Federation token request. |
| ServiceEndpoint | String | "" | The ServiceEndpoint is where clients can send requests to interact with the service, retrieve data, or perform operations. |
| ServiceName | String | "" | The ServiceName refers to the name of the service API selected by the user. |
| ServiceTimeout | Integer | 120 | The ServiceTimeout is the timeout to receive the full response from Anthropic API. |
| Suppress404NotFoundError | Boolean | true | When set to true, if a query results in an HTTP 404 error, a result set will still be created. When set to false, an error is logged instead and no result set is created. |
| ThrottleRateUnit | String | "PerMinute" | The unit of time for limiting API requests. Valid values are "PerSecond", "PerMinute", and "PerHour". When this setting is omitted, Anthropic uses "PerMinute", which matches the API Throttle Rate label in the connection manager. |
| Version | String | "2023-06-01" | The Version shown in the connection manager. It is sent with each request as the anthropic-version header. |
| WorkspaceId | String | "" | The optional Anthropic workspace ID. When provided, it is sent as the anthropic-workspace-id header. The Workload Identity Federation token request always includes workspace_id, using an empty string when this setting is blank. |